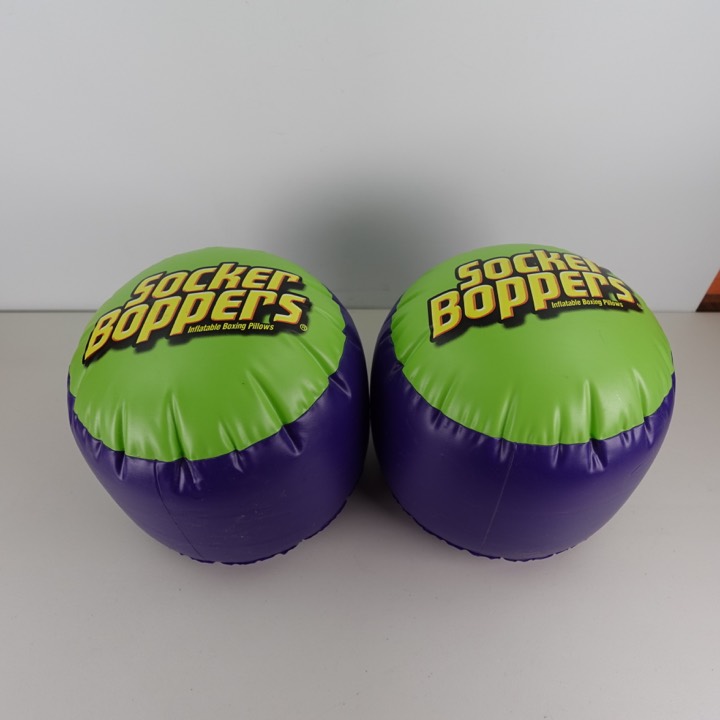
 01 · Socker Boppers
A pair photographed inflated and deflated. The model must count two pillows once and avoid claiming they hold air.
 Lakeview Listerfor eBay sellers
Early results · five items
We gave every setting the same 25 photos, then compared draft quality, time, and estimated AI cost.
Loading results…
The test items
01 · Socker BoppersA pair photographed inflated and deflated. The model must count two pillows once and avoid claiming they hold air.
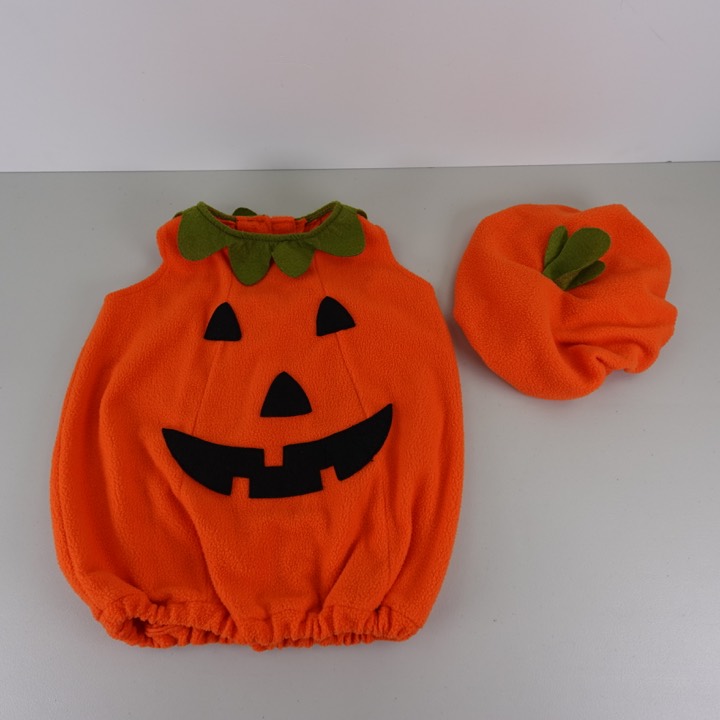 02 · Pumpkin costume
A Pottery Barn Kids 6–12 month body and matching hat. Brand, size, and both pieces matter.
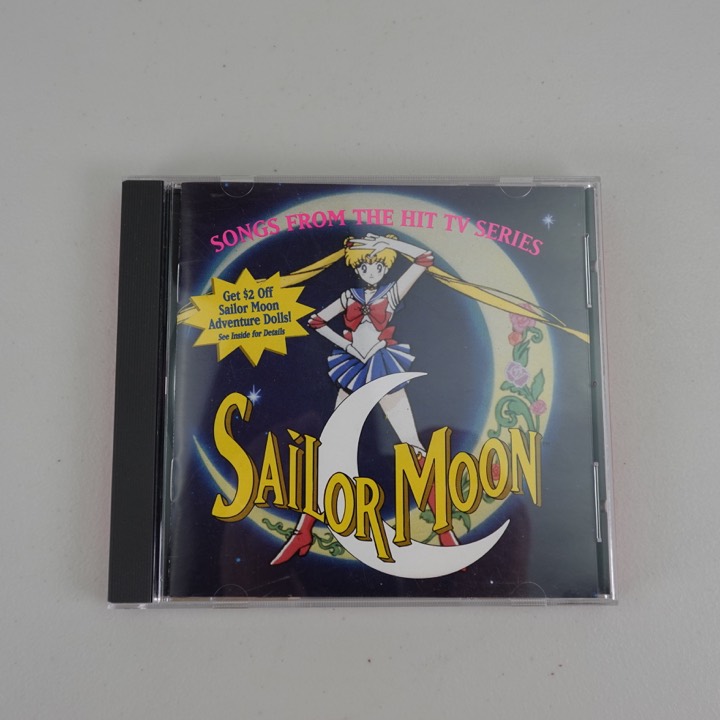 03 · Sailor Moon CD
An audio CD with a promotional-use mark on its insert. The photos cannot establish playback or disc-surface grade.
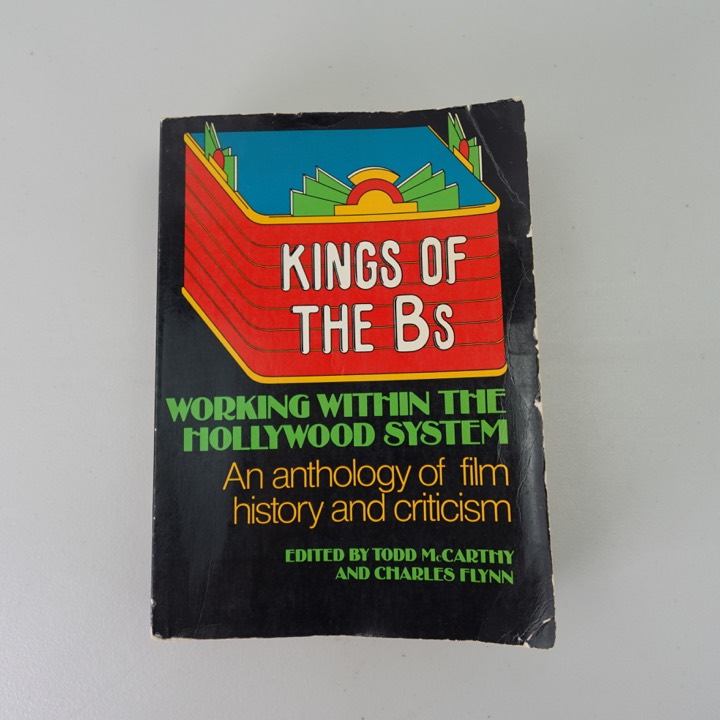 04 · Kings of the Bs
A worn 1975 Dutton first-edition paperback. The paperback ISBN must not be confused with the cloth edition.
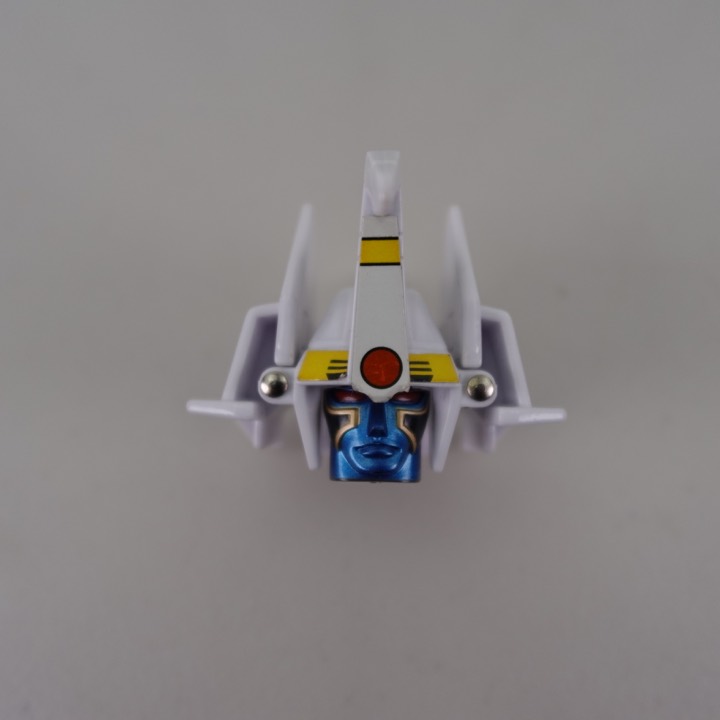 05 · Megazord crane head
A loose Power Rangers Shogun Megazord head/helmet piece, not a complete robot. We knew it was a crane head when scoring the listings, but did not tell the models.
One photo of each item is shown here. Every setting used all 25 photos.
Highlights
Each setting had one five-item attempt. These highlights show the trade-offs we saw; your inventory may produce different results.
01 · Low-cost settings
Gemini 3.5 Flash-Lite Minimal averaged 78.5 for less than a cent and 33 seconds per item. MiMo-V2.6 Flash On cost even less, but took 75 seconds and scored only 22.5 on the crane head. Qwen3.8 Omni Flash also stayed below a cent across its settings, with lower averages of 63–68.5 and longer times of 97–192 seconds.
02 · Value and item type
GLM-5.3-FlashX Maximum scored 81.5 at about three cents and 47 seconds per item, though its CD and book lacked eBay-required fields. Claude Sonnet 5.5 Medium scored 80.5 at 18 cents and 46 seconds. Muse Spark 1.3 Extra High scored 78 at ten cents and 80 seconds, including 75 on the difficult crane head. Grok 4.7 Extra High scored 79 at 14 cents but took 161 seconds.
03 · Highest averages
GPT-6 Astra Low had the highest average, 89.5, at about 57 cents and 49 seconds per item. GPT-6.1 Sol Low averaged 85.5 at eleven cents and 52 seconds. Both handled the crane head well, but each had two important fixes across the five drafts and a CD that failed eBay’s required-field check. A strong quality score does not mean a draft is ready to list.
04 · Reasoning settings
Sonnet 5.5 scored 80.5 at Medium reasoning versus 69 at Maximum, while average time rose from 46 to 254 seconds. Gemini Flash-Lite scored 78.5 at Minimal versus 67 at High. MiMo-V2.6 Pro UltraSpeed improved from 71.5 Off to 79.5 On, but took 70 rather than 43 seconds. Check the item scores that resemble what you sell.
Results
Scores are out of 100, and zero scores count in the average. Costs and times are averages per item, including attempts that did not produce a usable draft. Select any column heading to sort; select it again to reverse the order.Use Sort by and the direction button to arrange the results.
Results for older models remain in the table. “In current app build” shows which models are selectable in the current internal build. Public beta distribution remains paused.
Show models
Scroll sideways to see all five item scores.
| Loading results… | ||||||||||||
What the numbers mean
Every setting used the same five items and 25 photos, in Fast mode with standard-length descriptions, no seller notes, and no preset category. Tests spanned several app builds.
A completed listing could earn 100 points: correct item (25), key details (20), what is included (15), condition (15), category (10), writing (5), and avoiding unsupported claims (10). A zero means the model failed to make a usable draft or the draft earned no points. Both count in the average. We hid company and model names while scoring. “Important fixes” counts wrong or unsupported details a seller would need to correct. Separately, Ready / Not Ready checks whether a draft has eBay-required listing fields; it does not change the 100-point quality score.
Average time is the sum of item times divided by the number attempted, including failures. Fast mode processes multiple items at once, so this is not the time it takes to finish a batch. Average cost uses the same method. Costs are estimates, not provider bills. Kimi K3 costs were calculated from recorded tokens using Moonshot’s published K3 rates and five-minute cache pricing, checked September 23, 2026.
Five chosen items and one displayed attempt per setting are too few to establish which model is best overall. Settings tested on different app builds provide directional comparisons because the app and providers changed over time. Results may change with other products, new model versions, or app updates. AI helped us build the answer key and score the listings, so judgment may still be biased even though model names were hidden during scoring.